


使用Python实现文件复制程序的几种方法
在Python编程的世界里,文件操作是绕不开的基本功。无论你是处理文本数据、管理配置文件,还是搞数据分析,几乎天天都要和文件打交道。今天咱们就深入聊聊怎么用Python写一个简单的文件复制程序——别看它简单,吃透了这个过程,文件的读写操作你就算是真正入门了。 文件操作的重要性 文件操作,说穿了是每个
在Python编程的世界里,文件操作是绕不开的基本功。无论你是处理文本数据、管理配置文件,还是搞数据分析,几乎天天都要和文件打交道。今天咱们就深入聊聊怎么用Python写一个简单的文件复制程序——别看它简单,吃透了这个过程,文件的读写操作你就算是真正入门了。
文件操作的重要性
文件操作,说穿了是每个程序员都得掌握的看家本事。实际开发中你会遇到这些场景:
- 备份重要数据
- 处理日志文件
- 配置文件管理
- 数据迁移和同步
- 批量文件处理
通过实现文件复制程序,你不仅能练手Python文件I/O的核心概念,还能为更复杂的文件处理打下扎实的基础。
Python文件操作基础
动手写复制程序前,先把Python文件操作的基本概念过一遍。
文件打开模式
Python提供了好几种打开模式,最常见的就是这些:
# 基本的文件打开模式
file = open('filename.txt', 'r')    # 只读模式
file = open('filename.txt', 'w')    # 写入模式(覆盖)
file = open('filename.txt', 'a')    # 追加模式
file = open('filename.txt', 'r+')   # 读写模式
上下文管理器
为了保证文件能正确关闭,强烈推荐用上下文管理器:
with open('filename.txt', 'r') as file:
    content = file.read()
    # 文件会自动关闭
这招更安全可靠——就算程序中途报错,文件也能乖乖自己关上。
最简单的文件复制程序
先从最基础的版本开始,写一个朴素的文件复制函数:
def simple_copy(source_file, destination_file):
    """
    最简单的文件复制函数

    Args:
        source_file (str): 源文件路径
        destination_file (str): 目标文件路径
    """
    try:
        with open(source_file, 'r') as src:
            content = src.read()

        with open(destination_file, 'w') as dst:
            dst.write(content)

        print(f"✅ 文件已成功从 {source_file} 复制到 {destination_file}")

    except FileNotFoundError:
        print(f"❌ 错误:源文件 {source_file} 未找到")
    except PermissionError:
        print(f"❌ 错误:没有权限访问文件")
    except Exception as e:
        print(f"❌ 发生未知错误:{e}")

# 使用示例
if __name__ == "__main__":
    # 创建测试文件
    with open('test_source.txt', 'w') as f:
        f.write("这是测试内容nHello World!nPython文件操作")

    # 执行复制
    simple_copy('test_source.txt', 'test_destination.txt')
这个版本把文件复制的原理讲得明明白白:先读源文件全部内容,再一股脑写到目标文件。功能虽然简陋,但理解更复杂实现的门槛就靠它了。
改进版本 - 分块读取
碰到大文件时,一次性读进内存可能把内存撑爆。咱们改成分块读取:
def chunked_copy(source_file, destination_file, chunk_size=1024*1024):
    """
    分块读取的文件复制函数

    Args:
        source_file (str): 源文件路径
        destination_file (str): 目标文件路径
        chunk_size (int): 每次读取的字节数,默认1MB
    """
    try:
        with open(source_file, 'rb') as src, open(destination_file, 'wb') as dst:
            while True:
                chunk = src.read(chunk_size)
                if not chunk:
                    break
                dst.write(chunk)

        print(f"✅ 文件已成功从 {source_file} 复制到 {destination_file}")

    except FileNotFoundError:
        print(f"❌ 错误:源文件 {source_file} 未找到")
    except PermissionError:
        print(f"❌ 错误:没有权限访问文件")
    except Exception as e:
        print(f"❌ 发生未知错误:{e}")

# 使用示例
chunked_copy('large_file.bin', 'large_file_copy.bin')
这里用了二进制模式('rb'和'wb')——任何类型的文件都能处理,每次只读固定大小的数据块,内存占用稳稳的。
完整的功能版本
现在来打造一个功能完整的文件复制器,带进度条、错误处理,要啥有啥:
import os
import shutil
from pathlib import Path

class FileCopier:
    """文件复制器类"""

    def __init__(self):
        self.copied_bytes = 0
        self.total_bytes = 0

    def copy_with_progress(self, source_file, destination_file, show_progress=True):
        """
        带进度显示的文件复制

        Args:
            source_file (str): 源文件路径
            destination_file (str): 目标文件路径
            show_progress (bool): 是否显示进度
        """
        try:
            # 检查源文件是否存在
            if not os.path.exists(source_file):
                raise FileNotFoundError(f"源文件不存在: {source_file}")

            # 获取文件大小
            self.total_bytes = os.path.getsize(source_file)

            # 如果目标文件存在,询问是否覆盖
            if os.path.exists(destination_file):
                response = input(f"⚠️ 目标文件 {destination_file} 已存在,是否覆盖?(y/n): ")
                if response.lower() != 'y':
                    print("❌ 操作已取消")
                    return False

            # 执行复制
            self._copy_file(source_file, destination_file, show_progress)

            print(f"n✅ 文件复制完成!")
            print(f"? 源文件: {source_file}")
            print(f"? 目标文件: {destination_file}")
            print(f"? 文件大小: {self._format_bytes(self.total_bytes)}")

            return True

        except FileNotFoundError as e:
            print(f"❌ 错误:{e}")
        except PermissionError:
            print(f"❌ 错误:没有权限访问文件")
        except KeyboardInterrupt:
            print("n? 用户中断了操作")
        except Exception as e:
            print(f"❌ 发生未知错误:{e}")

        return False

    def _copy_file(self, source_file, destination_file, show_progress):
        """执行文件复制的核心方法"""
        chunk_size = 1024 * 64  # 64KB chunks
        self.copied_bytes = 0

        with open(source_file, 'rb') as src, open(destination_file, 'wb') as dst:
            while True:
                chunk = src.read(chunk_size)
                if not chunk:
                    break

                dst.write(chunk)
                self.copied_bytes += len(chunk)

                if show_progress and self.total_bytes > 0:
                    self._show_progress()

    def _show_progress(self):
        """显示复制进度"""
        if self.total_bytes > 0:
            progress = (self.copied_bytes / self.total_bytes) * 100
            bar_length = 30
            filled_length = int(bar_length * progress // 100)
            bar = '█' * filled_length + '-' * (bar_length - filled_length)

            print(f'r进度: |{bar}| {progress:.1f}% ({self._format_bytes(self.copied_bytes)}/{self._format_bytes(self.total_bytes)})',
                  end='', flush=True)

    def _format_bytes(self, bytes_count):
        """格式化字节大小显示"""
        for unit in ['B', 'KB', 'MB', 'GB', 'TB']:
            if bytes_count < 1024.0:
                return f"{bytes_count:.1f}{unit}"
            bytes_count /= 1024.0
        return f"{bytes_count:.1f}PB"

# 使用示例
def main():
    copier = FileCopier()

    # 创建测试文件
    test_content = "这是一个测试文件的内容n" * 1000
    with open('test_large.txt', 'w', encoding='utf-8') as f:
        f.write(test_content)

    # 执行复制
    copier.copy_with_progress('test_large.txt', 'test_large_copy.txt')

if __name__ == "__main__":
    main()
这个完整版塞进了这些好东西:
- 进度条显示
- 文件覆盖确认
- 异常处理
- 字节单位格式化
- 用户友好的界面
高级功能扩展
批量文件复制
有时候需要批量复制好几个文件,咱们来搞个批量操作:
import glob
import os
from pathlib import Path

class BatchFileCopier(FileCopier):
    """批量文件复制器"""

    def copy_files_by_pattern(self, pattern, destination_dir):
        """
        根据模式批量复制文件

        Args:
            pattern (str): 文件匹配模式,如 "*.txt"
            destination_dir (str): 目标目录
        """
        files = glob.glob(pattern)
        if not files:
            print(f"❌ 没有找到匹配的文件: {pattern}")
            return False

        # 确保目标目录存在
        os.makedirs(destination_dir, exist_ok=True)

        print(f"? 找到 {len(files)} 个文件需要复制")

        success_count = 0
        for file_path in files:
            filename = os.path.basename(file_path)
            dest_path = os.path.join(destination_dir, filename)

            print(f"n? 正在复制: {file_path}")
            if self.copy_with_progress(file_path, dest_path, show_progress=False):
                success_count += 1

        print(f"n? 批量复制完成!成功: {success_count}/{len(files)}")
        return success_count == len(files)

    def copy_directory(self, source_dir, destination_dir, recursive=True):
        """
        复制整个目录

        Args:
            source_dir (str): 源目录
            destination_dir (str): 目标目录
            recursive (bool): 是否递归复制子目录
        """
        source_path = Path(source_dir)
        dest_path = Path(destination_dir)

        if not source_path.exists():
            print(f"❌ 源目录不存在: {source_dir}")
            return False

        if not source_path.is_dir():
            print(f"❌ 源路径不是目录: {source_dir}")
            return False

        # 创建目标目录
        dest_path.mkdir(parents=True, exist_ok=True)

        copied_files = 0
        total_files = 0

        # 遍历源目录
        for item in source_path.rglob('*') if recursive else source_path.iterdir():
            if item.is_file():
                total_files += 1
                relative_path = item.relative_to(source_path)
                dest_item = dest_path / relative_path

                # 创建必要的子目录
                dest_item.parent.mkdir(parents=True, exist_ok=True)

                print(f"? 正在复制: {item}")
                if self.copy_with_progress(str(item), str(dest_item), show_progress=False):
                    copied_files += 1

        print(f"n? 目录复制完成!成功: {copied_files}/{total_files}")
        return copied_files == total_files

# 使用示例
def batch_example():
    copier = BatchFileCopier()

    # 创建测试文件
    os.makedirs('test_folder', exist_ok=True)
    for i in range(5):
        with open(f'test_folder/file_{i}.txt', 'w') as f:
            f.write(f"这是第{i}个测试文件")

    # 批量复制特定类型文件
    copier.copy_files_by_pattern('test_folder/*.txt', 'backup_folder')

    # 复制整个目录
    copier.copy_directory('test_folder', 'full_backup')

if __name__ == "__main__":
    batch_example()
添加文件校验功能
要确保复制过去的文件完全没损坏,可以加上MD5校验:
import hashlib

class VerifiedFileCopier(BatchFileCopier):
    """带验证的文件复制器"""

    def get_file_hash(self, file_path, algorithm='md5'):
        """
        计算文件的哈希值

        Args:
            file_path (str): 文件路径
            algorithm (str): 哈希算法

        Returns:
            str: 文件哈希值
        """
        hash_obj = hashlib.new(algorithm)

        with open(file_path, 'rb') as f:
            for chunk in iter(lambda: f.read(4096), b""):
                hash_obj.update(chunk)

        return hash_obj.hexdigest()

    def copy_with_verification(self, source_file, destination_file, verify=True):
        """
        带验证的文件复制

        Args:
            source_file (str): 源文件路径
            destination_file (str): 目标文件路径
            verify (bool): 是否验证文件完整性
        """
        # 先执行普通复制
        if not self.copy_with_progress(source_file, destination_file):
            return False

        # 如果需要验证
        if verify:
            print("? 正在校验文件完整性...")
            try:
                source_hash = self.get_file_hash(source_file)
                dest_hash = self.get_file_hash(destination_file)

                if source_hash == dest_hash:
                    print("✅ 文件完整性校验通过")
                    return True
                else:
                    print("❌ 文件完整性校验失败")
                    return False

            except Exception as e:
                print(f"❌ 校验过程中发生错误: {e}")
                return False

        return True

# 使用示例
def verification_example():
    copier = VerifiedFileCopier()

    # 创建测试文件
    with open('verify_test.txt', 'w') as f:
        f.write("这是用于验证的测试文件内容" * 100)

    # 带验证的复制
    copier.copy_with_verification('verify_test.txt', 'verify_test_copy.txt')

if __name__ == "__main__":
    verification_example()
性能优化技巧
处理大文件或大量文件时,性能优化就成关键了。下面几个技巧相当实用。
使用shutil模块
Python标准库里的shutil模块自带高效的文件操作函数:
import shutil
import os

def optimized_copy(source_file, destination_file):
    """
    使用shutil进行高效文件复制

    Args:
        source_file (str): 源文件路径
        destination_file (str): 目标文件路径
    """
    try:
        # 对于小文件,直接复制
        file_size = os.path.getsize(source_file)

        if file_size < 1024 * 1024:  # 小于1MB
            shutil.copy2(source_file, destination_file)
        else:
            # 对于大文件,使用copyfileobj
            with open(source_file, 'rb') as src, open(destination_file, 'wb') as dst:
                shutil.copyfileobj(src, dst, length=64*1024)  # 64KB缓冲区

        print(f"✅ 文件复制完成")
        return True

    except Exception as e:
        print(f"❌ 复制失败: {e}")
        return False
并行处理
要复制大量文件,并行处理能让速度起飞:
import concurrent.futures
import os
from pathlib import Path

class ParallelFileCopier(VerifiedFileCopier):
    """并行文件复制器"""

    def copy_files_parallel(self, file_pairs, max_workers=4):
        """
        并行复制多个文件

        Args:
            file_pairs (list): 源文件和目标文件的元组列表
            max_workers (int): 最大工作线程数
        """
        with concurrent.futures.ThreadPoolExecutor(max_workers=max_workers) as executor:
            # 提交所有任务
            future_to_pair = {
                executor.submit(self.copy_with_progress, src, dst, False): (src, dst)
                for src, dst in file_pairs
            }

            # 收集结果
            completed = 0
            total = len(file_pairs)

            for future in concurrent.futures.as_completed(future_to_pair):
                src, dst = future_to_pair[future]
                try:
                    result = future.result()
                    if result:
                        completed += 1
                        print(f"✅ 完成: {src} -> {dst}")
                    else:
                        print(f"❌ 失败: {src} -> {dst}")
                except Exception as e:
                    print(f"❌ 复制 {src} 时发生错误: {e}")

            print(f"n? 并行复制完成!成功: {completed}/{total}")

# 使用示例
def parallel_example():
    copier = ParallelFileCopier()

    # 准备测试文件
    test_files = []
    for i in range(10):
        filename = f'parallel_test_{i}.txt'
        with open(filename, 'w') as f:
            f.write(f"这是第{i}个并行测试文件" * 50)
        test_files.append((filename, f'parallel_copy_{i}.txt'))

    # 并行复制
    copier.copy_files_parallel(test_files, max_workers=3)

if __name__ == "__main__":
    parallel_example()
错误处理最佳实践
一个健壮的文件复制程序,错误处理机制必须到位:
import logging
import time
from enum import Enum

class CopyResult(Enum):
    SUCCESS = "success"
    FILE_NOT_FOUND = "file_not_found"
    PERMISSION_DENIED = "permission_denied"
    DISK_FULL = "disk_full"
    INTERRUPTED = "interrupted"
    UNKNOWN_ERROR = "unknown_error"

class RobustFileCopier(ParallelFileCopier):
    """健壮的文件复制器"""

    def __init__(self, retry_attempts=3, retry_delay=1):
        super().__init__()
        self.retry_attempts = retry_attempts
        self.retry_delay = retry_delay
        self.logger = self._setup_logger()

    def _setup_logger(self):
        """设置日志记录器"""
        logger = logging.getLogger('FileCopier')
        logger.setLevel(logging.INFO)

        handler = logging.StreamHandler()
        formatter = logging.Formatter('%(asctime)s - %(levelname)s - %(message)s')
        handler.setFormatter(formatter)
        logger.addHandler(handler)

        return logger

    def copy_with_retry(self, source_file, destination_file):
        """
        带重试机制的文件复制

        Args:
            source_file (str): 源文件路径
            destination_file (str): 目标文件路径
        """
        for attempt in range(self.retry_attempts):
            try:
                self.logger.info(f"尝试复制 {source_file} 到 {destination_file} (第{attempt+1}次)")

                if self.copy_with_progress(source_file, destination_file):
                    self.logger.info("✅ 文件复制成功")
                    return CopyResult.SUCCESS

            except FileNotFoundError:
                self.logger.error(f"❌ 源文件未找到: {source_file}")
                return CopyResult.FILE_NOT_FOUND

            except PermissionError:
                self.logger.error(f"❌ 权限不足: {source_file}")
                return CopyResult.PERMISSION_DENIED

            except OSError as e:
                if "No space left on device" in str(e):
                    self.logger.error("❌ 磁盘空间不足")
                    return CopyResult.DISK_FULL
                else:
                    self.logger.error(f"❌ 系统错误: {e}")

            except KeyboardInterrupt:
                self.logger.warning("? 用户中断操作")
                return CopyResult.INTERRUPTED

            except Exception as e:
                self.logger.error(f"❌ 未知错误: {e}")

                if attempt < self.retry_attempts - 1:
                    self.logger.info(f"等待 {self.retry_delay} 秒后重试...")
                    time.sleep(self.retry_delay)
                else:
                    return CopyResult.UNKNOWN_ERROR

        return CopyResult.UNKNOWN_ERROR

# 使用示例
def robust_example():
    copier = RobustFileCopier(retry_attempts=3, retry_delay=2)

    # 创建测试文件
    with open('robust_test.txt', 'w') as f:
        f.write("这是健壮性测试文件" * 100)

    # 执行带重试的复制
    result = copier.copy_with_retry('robust_test.txt', 'robust_test_copy.txt')
    print(f"复制结果: {result.value}")

if __name__ == "__main__":
    robust_example()
实际应用场景
来看看文件复制程序在实际中能派上哪些用场。
日志文件轮转
import datetime
import gzip

class LogRotator(RobustFileCopier):
    """日志文件轮转器"""

    def rotate_log(self, log_file, backup_count=5, compress=True):
        """
        轮转日志文件

        Args:
            log_file (str): 日志文件路径
            backup_count (int): 保留的备份数量
            compress (bool): 是否压缩旧日志
        """
        if not os.path.exists(log_file):
            self.logger.info(f"日志文件不存在: {log_file}")
            return

        # 创建时间戳
        timestamp = datetime.datetime.now().strftime("%Y%m%d_%H%M%S")

        # 备份当前日志
        backup_name = f"{log_file}.{timestamp}"
        if self.copy_with_retry(log_file, backup_name) != CopyResult.SUCCESS:
            return

        # 压缩备份文件(如果需要)
        if compress:
            compressed_name = f"{backup_name}.gz"
            try:
                with open(backup_name, 'rb') as f_in:
                    with gzip.open(compressed_name, 'wb') as f_out:
                        shutil.copyfileobj(f_in, f_out)
                os.remove(backup_name)  # 删除未压缩的备份
                backup_name = compressed_name
            except Exception as e:
                self.logger.error(f"压缩失败: {e}")

        # 清理旧的备份文件
        self._cleanup_old_backups(log_file, backup_count, compress)

        # 清空原日志文件
        try:
            with open(log_file, 'w'):
                pass  # 清空文件
            self.logger.info("✅ 日志轮转完成")
        except Exception as e:
            self.logger.error(f"清空日志文件失败: {e}")

    def _cleanup_old_backups(self, log_file, backup_count, compress):
        """清理旧的备份文件"""
        pattern = f"{log_file}.*"
        if compress:
            pattern += ".gz"

        backups = glob.glob(pattern)
        backups.sort(reverse=True)  # 按时间倒序排列

        # 删除超出保留数量的备份
        for old_backup in backups[backup_count:]:
            try:
                os.remove(old_backup)
                self.logger.info(f"删除旧备份: {old_backup}")
            except Exception as e:
                self.logger.error(f"删除备份失败 {old_backup}: {e}")

# 使用示例
def log_rotation_example():
    rotator = LogRotator()

    # 创建模拟日志文件
    with open('app.log', 'w') as f:
        f.write("这是应用日志内容n" * 1000)

    # 执行日志轮转
    rotator.rotate_log('app.log', backup_count=3, compress=True)

if __name__ == "__main__":
    log_rotation_example()
配置文件备份
import json
import yaml

class ConfigBackupManager(RobustFileCopier):
    """配置文件备份管理器"""

    def backup_configs(self, config_paths, backup_dir="config_backup"):
        """
        备份多个配置文件

        Args:
            config_paths (list): 配置文件路径列表
            backup_dir (str): 备份目录
        """
        # 创建备份目录
        os.makedirs(backup_dir, exist_ok=True)

        # 创建备份信息文件
        backup_info = {
            "timestamp": datetime.datetime.now().isoformat(),
            "configs": {},
            "system_info": {
                "platform": os.name,
                "cwd": os.getcwd()
            }
        }

        success_count = 0
        for config_path in config_paths:
            if os.path.exists(config_path):
                filename = os.path.basename(config_path)
                backup_path = os.path.join(backup_dir, filename)

                # 执行备份
                result = self.copy_with_retry(config_path, backup_path)
                if result == CopyResult.SUCCESS:
                    success_count += 1

                    # 记录配置文件信息
                    backup_info["configs"][filename] = {
                        "original_path": config_path,
                        "backup_path": backup_path,
                        "size": os.path.getsize(config_path),
                        "modified_time": os.path.getmtime(config_path)
                    }

        # 保存备份信息
        info_file = os.path.join(backup_dir, "backup_info.json")
        with open(info_file, 'w') as f:
            json.dump(backup_info, f, indent=2, default=str)

        print(f"✅ 配置文件备份完成!成功: {success_count}/{len(config_paths)}")
        print(f"? 备份位置: {os.path.abspath(backup_dir)}")

    def restore_config(self, backup_dir, config_name):
        """
        恢复配置文件

        Args:
            backup_dir (str): 备份目录
            config_name (str): 配置文件名
        """
        backup_path = os.path.join(backup_dir, config_name)
        if not os.path.exists(backup_path):
            print(f"❌ 备份文件不存在: {backup_path}")
            return False

        # 从备份信息中获取原始路径
        info_file = os.path.join(backup_dir, "backup_info.json")
        if os.path.exists(info_file):
            with open(info_file, 'r') as f:
                backup_info = json.load(f)

            original_path = backup_info.get("configs", {}).get(config_name, {}).get("original_path")
            if original_path:
                return self.copy_with_retry(backup_path, original_path) == CopyResult.SUCCESS

        print("❌ 无法确定原始路径,请手动指定")
        return False

# 使用示例
def config_backup_example():
    manager = ConfigBackupManager()

    # 创建测试配置文件
    test_configs = ['app.conf', 'database.yml', 'settings.json']
    for config in test_configs:
        with open(config, 'w') as f:
            if config.endswith('.json'):
                json.dump({"setting": "value"}, f)
            elif config.endswith('.yml'):
                f.write("setting: valuen")
            else:
                f.write("setting=valuen")

    # 执行备份
    manager.backup_configs(test_configs)

    # 模拟恢复
    # manager.restore_config('config_backup', 'app.conf')

if __name__ == "__main__":
    config_backup_example()
性能对比分析
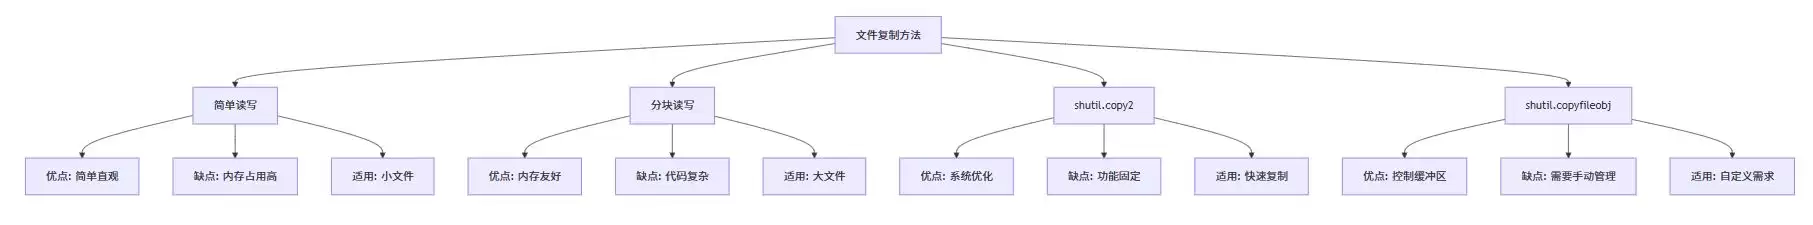
下面这张图展示了不同复制方法的性能差异:
最佳实践总结
综合上面的代码示例和实践经验,总结出下面几条黄金准则。
1. 选择合适的文件操作方式
- 小文件:直接读写或使用
shutil.copy2 - 大文件:分块读写或使用
shutil.copyfileobj - 特殊需求:自定义实现
2. 完善的错误处理
# 推荐的错误处理模式
try:
    # 文件操作
    pass
except FileNotFoundError:
    # 处理文件不存在
    pass
except PermissionError:
    # 处理权限问题
    pass
except OSError as e:
    # 处理系统相关错误
    pass
except Exception as e:
    # 处理其他异常
    pass
3. 资源管理
始终用上下文管理器保证文件正确关闭:
with open('file.txt', 'r') as f:
    content = f.read()
# 文件自动关闭
4. 性能优化策略
- 合理设置缓冲区大小
- 非文本文件用二进制模式
- 大量文件考虑多线程
- 利用系统级的复制函数
5. 用户体验优化
- 清晰的进度反馈
- 合理的交互提示
- 详细的日志记录
- 优雅的错误信息
结语
这篇文章从最朴素的文件复制程序出发,一路进化成了一个功能齐全、性能靠谱、用户体验也拿得出手的工具。你不仅把Python文件操作的基础打牢了,还见识了不少进阶技巧和最佳实践。
文件复制这个活儿看起来简单,但里面藏着不少值得深挖的技术门道。希望这些内容能帮你在Python文件操作的路上走得更顺,也期待你把它们用到实际项目里,创造更多有价值的应用。
记住,编程最后拼的不仅是写代码,更是解决问题的思路和方法。多动手、多琢磨,你会发现Python文件操作的世界远比想象中精彩。




















火山引擎是字节跳动旗下企业级云与AI服务平台。聚焦大模型核心能力,依托字节自研豆包多模态大模型,凭借火山方舟一站式平台,提供模型精调、推理部署、智能应用搭建等全链路服务,结合高性能AI算力,助力各行业快速落地大模型数字化与智能化应用。








AirBuddy 3 是面向 macOS 的蓝牙外设增强工具,可集中查看 AirPods、Beats 与苹果设备电量,提供快速连接、播放控制、电量提醒、桌面小组件和多台 Mac 外设接力等功能。

AirServer macOS版可把 Mac 转换为无线投屏接收端,通过 AirPlay 或 Google Cast 接收手机、平板和电脑画面,并支持多设备同时连接、高清镜像及会话录制,适合家庭娱乐、课堂教学、会议演示和应用展示。



Autodesk Maya 是面向影视、电视、动画和游戏行业的专业三维制作软件,集多边形与 NURBS 建模、角色绑定、关键帧和动作捕捉动画、Bifrost 特效模拟、材质开发及 Arnold 渲染于一体,

AirServer Windows版可把电脑变成AirPlay、Google Cast和Miracast无线投屏接收端,适合会议演示、课堂教学及家庭大屏分享。发送设备通常无需另装客户端,并可同时接收和智能排列多个镜像会话。